News & Updates
The latest news and updates from companies in the WLTH portfolio.
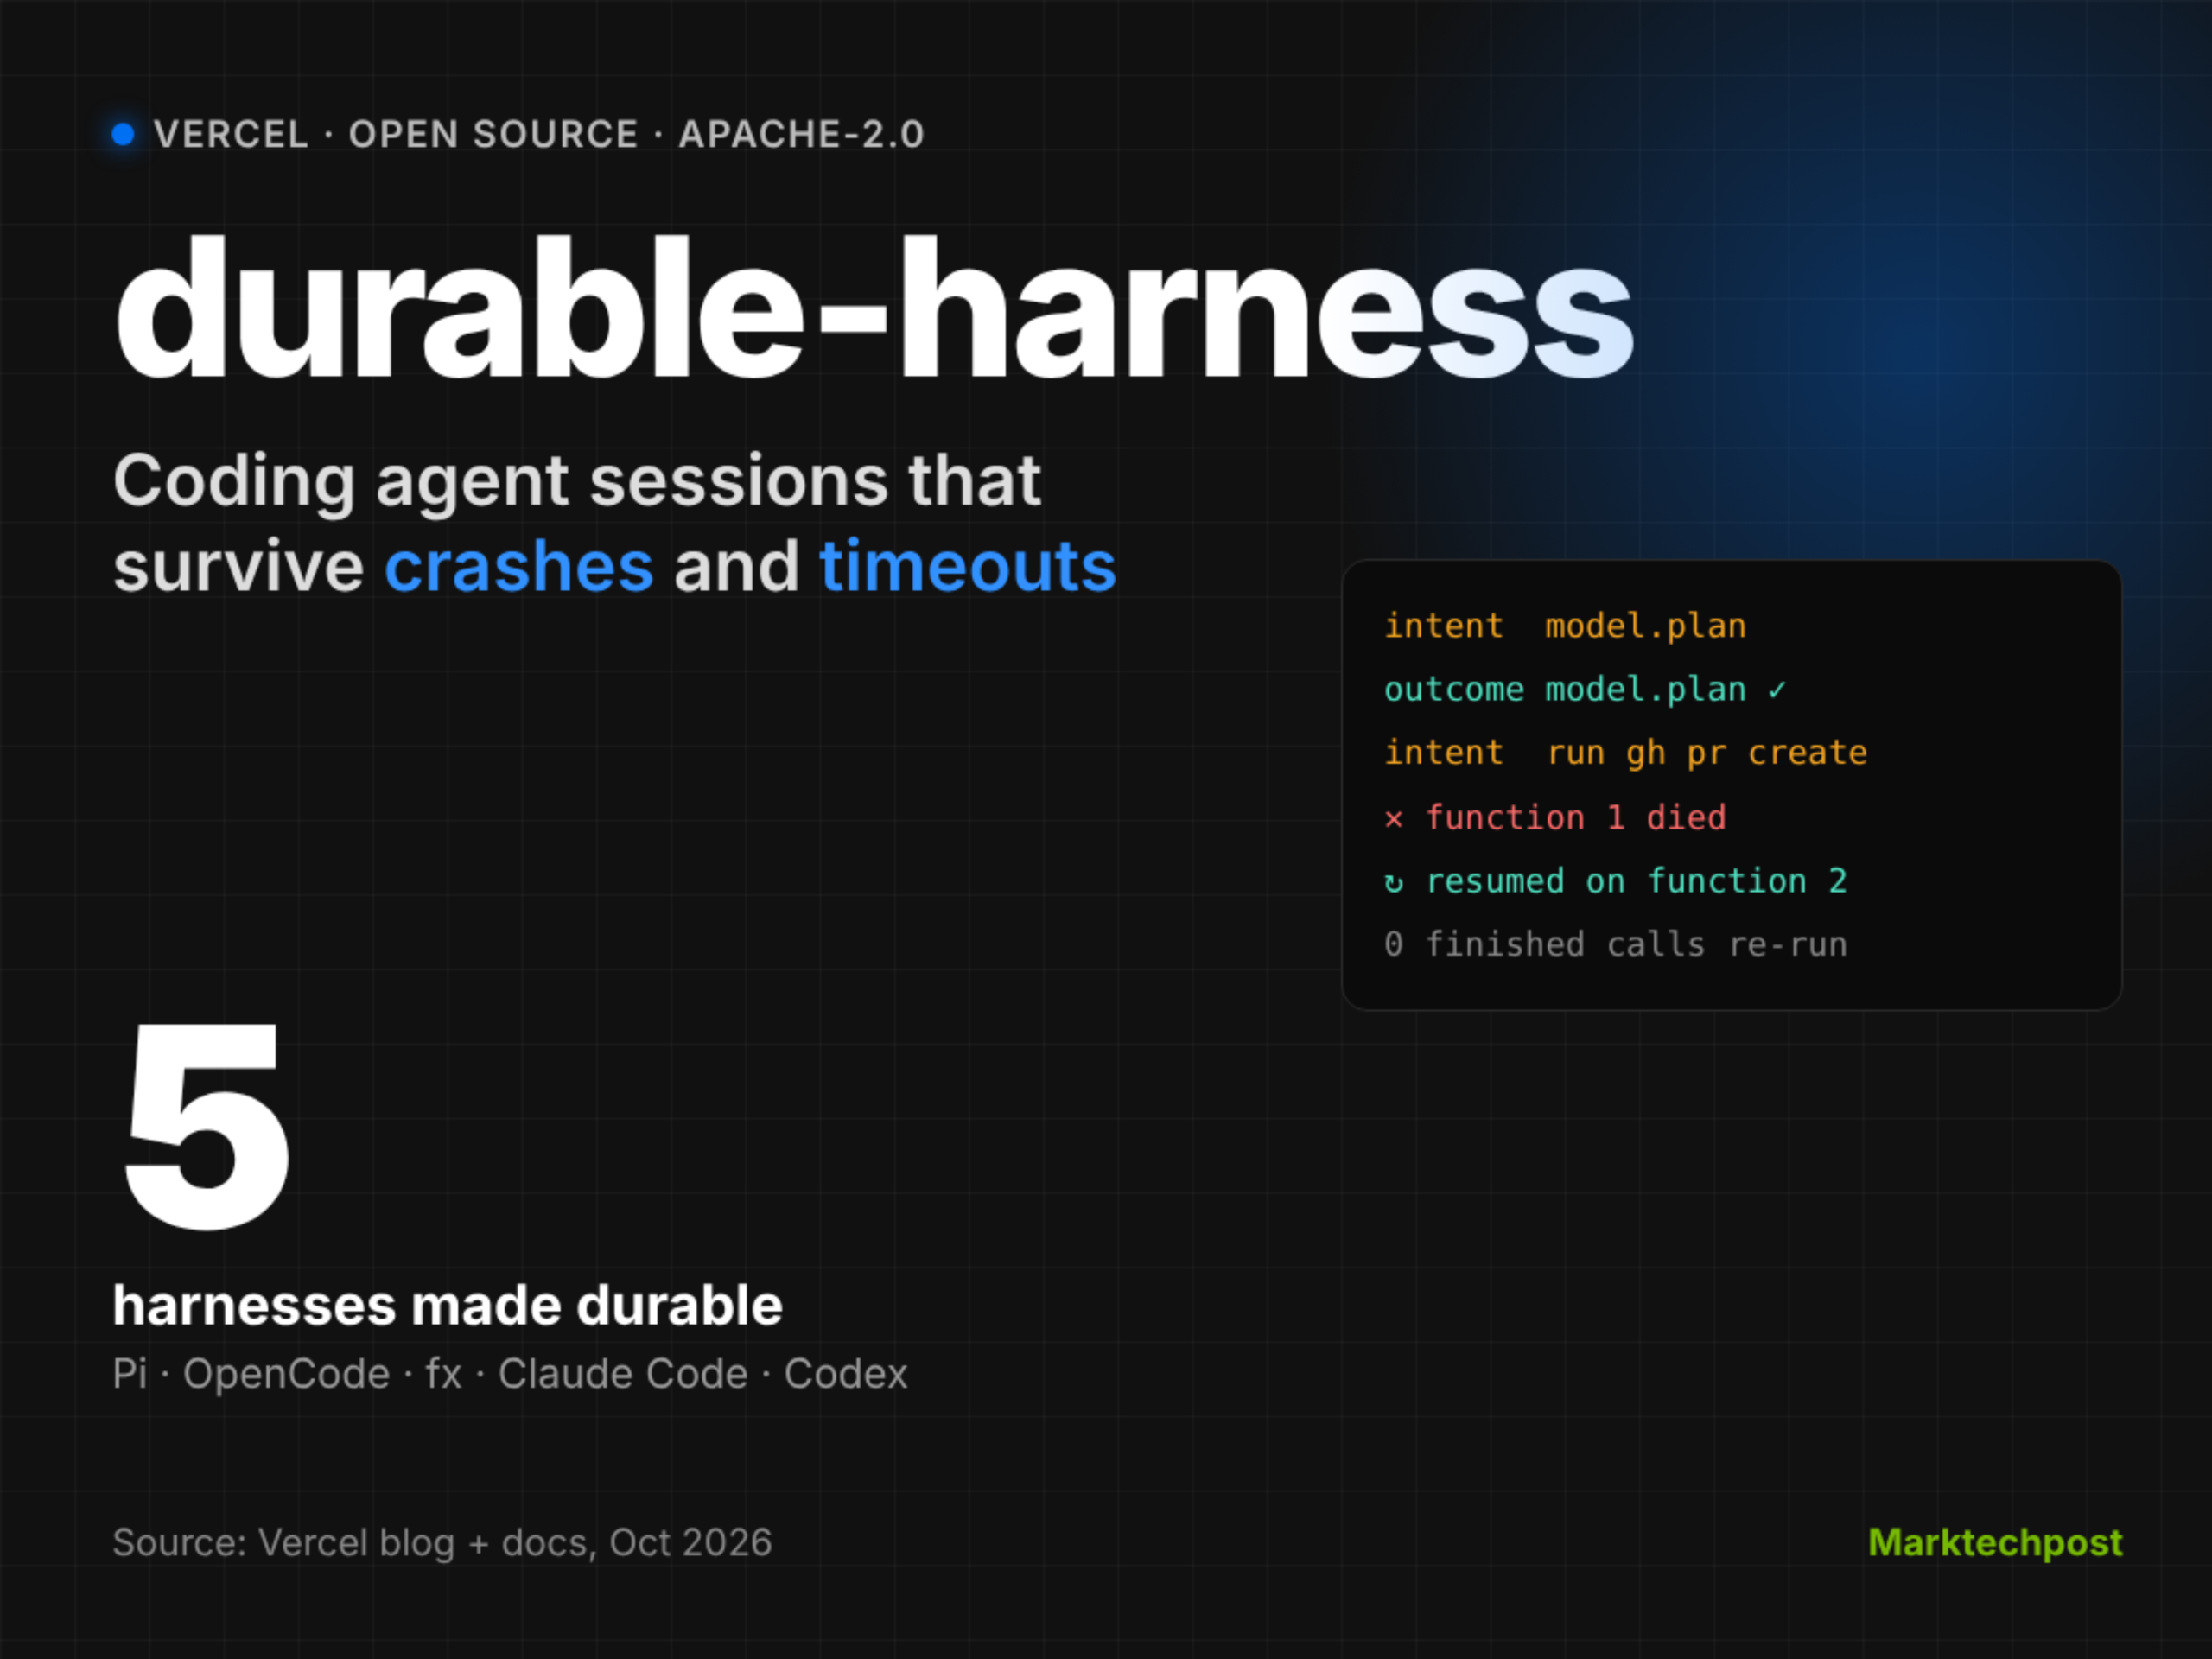
Vercel Open-Sources durable-harness for Crash-Proof Coding Agents
Vercel has released durable-harness, an open-source package that keeps coding agent sessions alive through crashes and timeouts. Vercel durable-harness wraps existing harnesses, including Pi, OpenCode, Claude Code and Codex, without changing them. Each session lives in a durable log. A dead function no longer means lost work. For teams moving agents off laptops and into the cloud, that closes a real gap. TL;DR * Size: npm package, version 0.0.x, Apache-2.0. Adapters cover 5 harnesses: Pi, OpenCode, fx, Claude Code, Codex. * Runs on: Vercel Functions plus Vercel Queues, Node.js 22+ with Postgres, or laptop files. Claude Code and Codex need a Vercel Sandbox. * Performance: No latency or throughput benchmarks published. All recovery claims are self-reported by Vercel. * Best: Finished model and tool calls are read back from the log, never re-run or billed twice. * Worst: Experimental 0.0.x API. Claude Code and Codex run only in a Vercel Sandbox, even self-hosted. What is durable-harness? durable-harness is a set of adapters from Vercel that store a harness session in a Workflow SDK World. A World bundles storage, a queue and a stream behind one interface. The package uses the same machinery that powers Vercel's Workflow SDK. Why do coding agents lose work in the cloud? Harnesses like Pi and Claude Code were designed as long-lived local processes. They keep the session in memory. Locally, the workspace and history sit on the same disk, so resuming takes 1 prompt. In the cloud, a VM with persistent storage does not track which calls completed. Vercel team notes a failed turn or network error then means lost work. How does durable-harness work? It writes each step of a turn to a durable log. Before a model or tool call runs, it records an intent. When the call finishes, it records the outcome. Each turn is backed by a message on Vercel Queues. If the function dies, the queue hands the turn to a new function. That function reads the log and continues. After a crash, the log shows what finished, what was running and what never started: * Completed calls are read from the log, so finished model tokens are not billed again. * replay: 'safe' tools, such as lookups, can run again. * replay: 'never' tools, such as refunds, never run twice. The model is told the call may have happened. Harness session files are mirrored into the log as well. That covers Claude Code's transcript, Codex's rollout and OpenCode's event store. Where do files and shell commands run? Model-chosen commands never run on the function's own disk. The tools docs list 3 workspace options: * keeps files in the session log, with a bash-compatible shell and no network. It holds about 500 files. * keeps scratch files in memory and clears them every turn. * gives each session a Vercel Sandbox, with /workspace on a Drive. Typed JSON documents, such as a to-do list, also live in the log. Each holds at most 64 KB. Where can you run durable-harness? The agent code stays the same across Worlds: * Vercel: the Vercel World, with every session traced in Agent Runs. * Local: files on your machine, with no configuration. * Self-hosted: the Postgres World, version 5.0.4 or later, on Node.js 22+. Vercel's blog also lists MongoDB, Redis and Turso. 2 environment variables, WORKFLOW_TARGET_WORLD and WORKFLOW_POSTGRES_URL, move an agent to Postgres. How does durable-harness compare? Key Takeaways * durable-harness logs every model and tool call, then resumes crashed turns on a new function. * Finished calls are never repeated, so tokens are not billed twice. * Pi and OpenCode run in your function; Claude Code and Codex need a Vercel Sandbox. * Self-hosting works with 2 env vars and a Postgres World. * It is 0.0.x and experimental, with no published benchmarks. Check out the GitHub repo, docs and Vercel's announcement. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don't forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
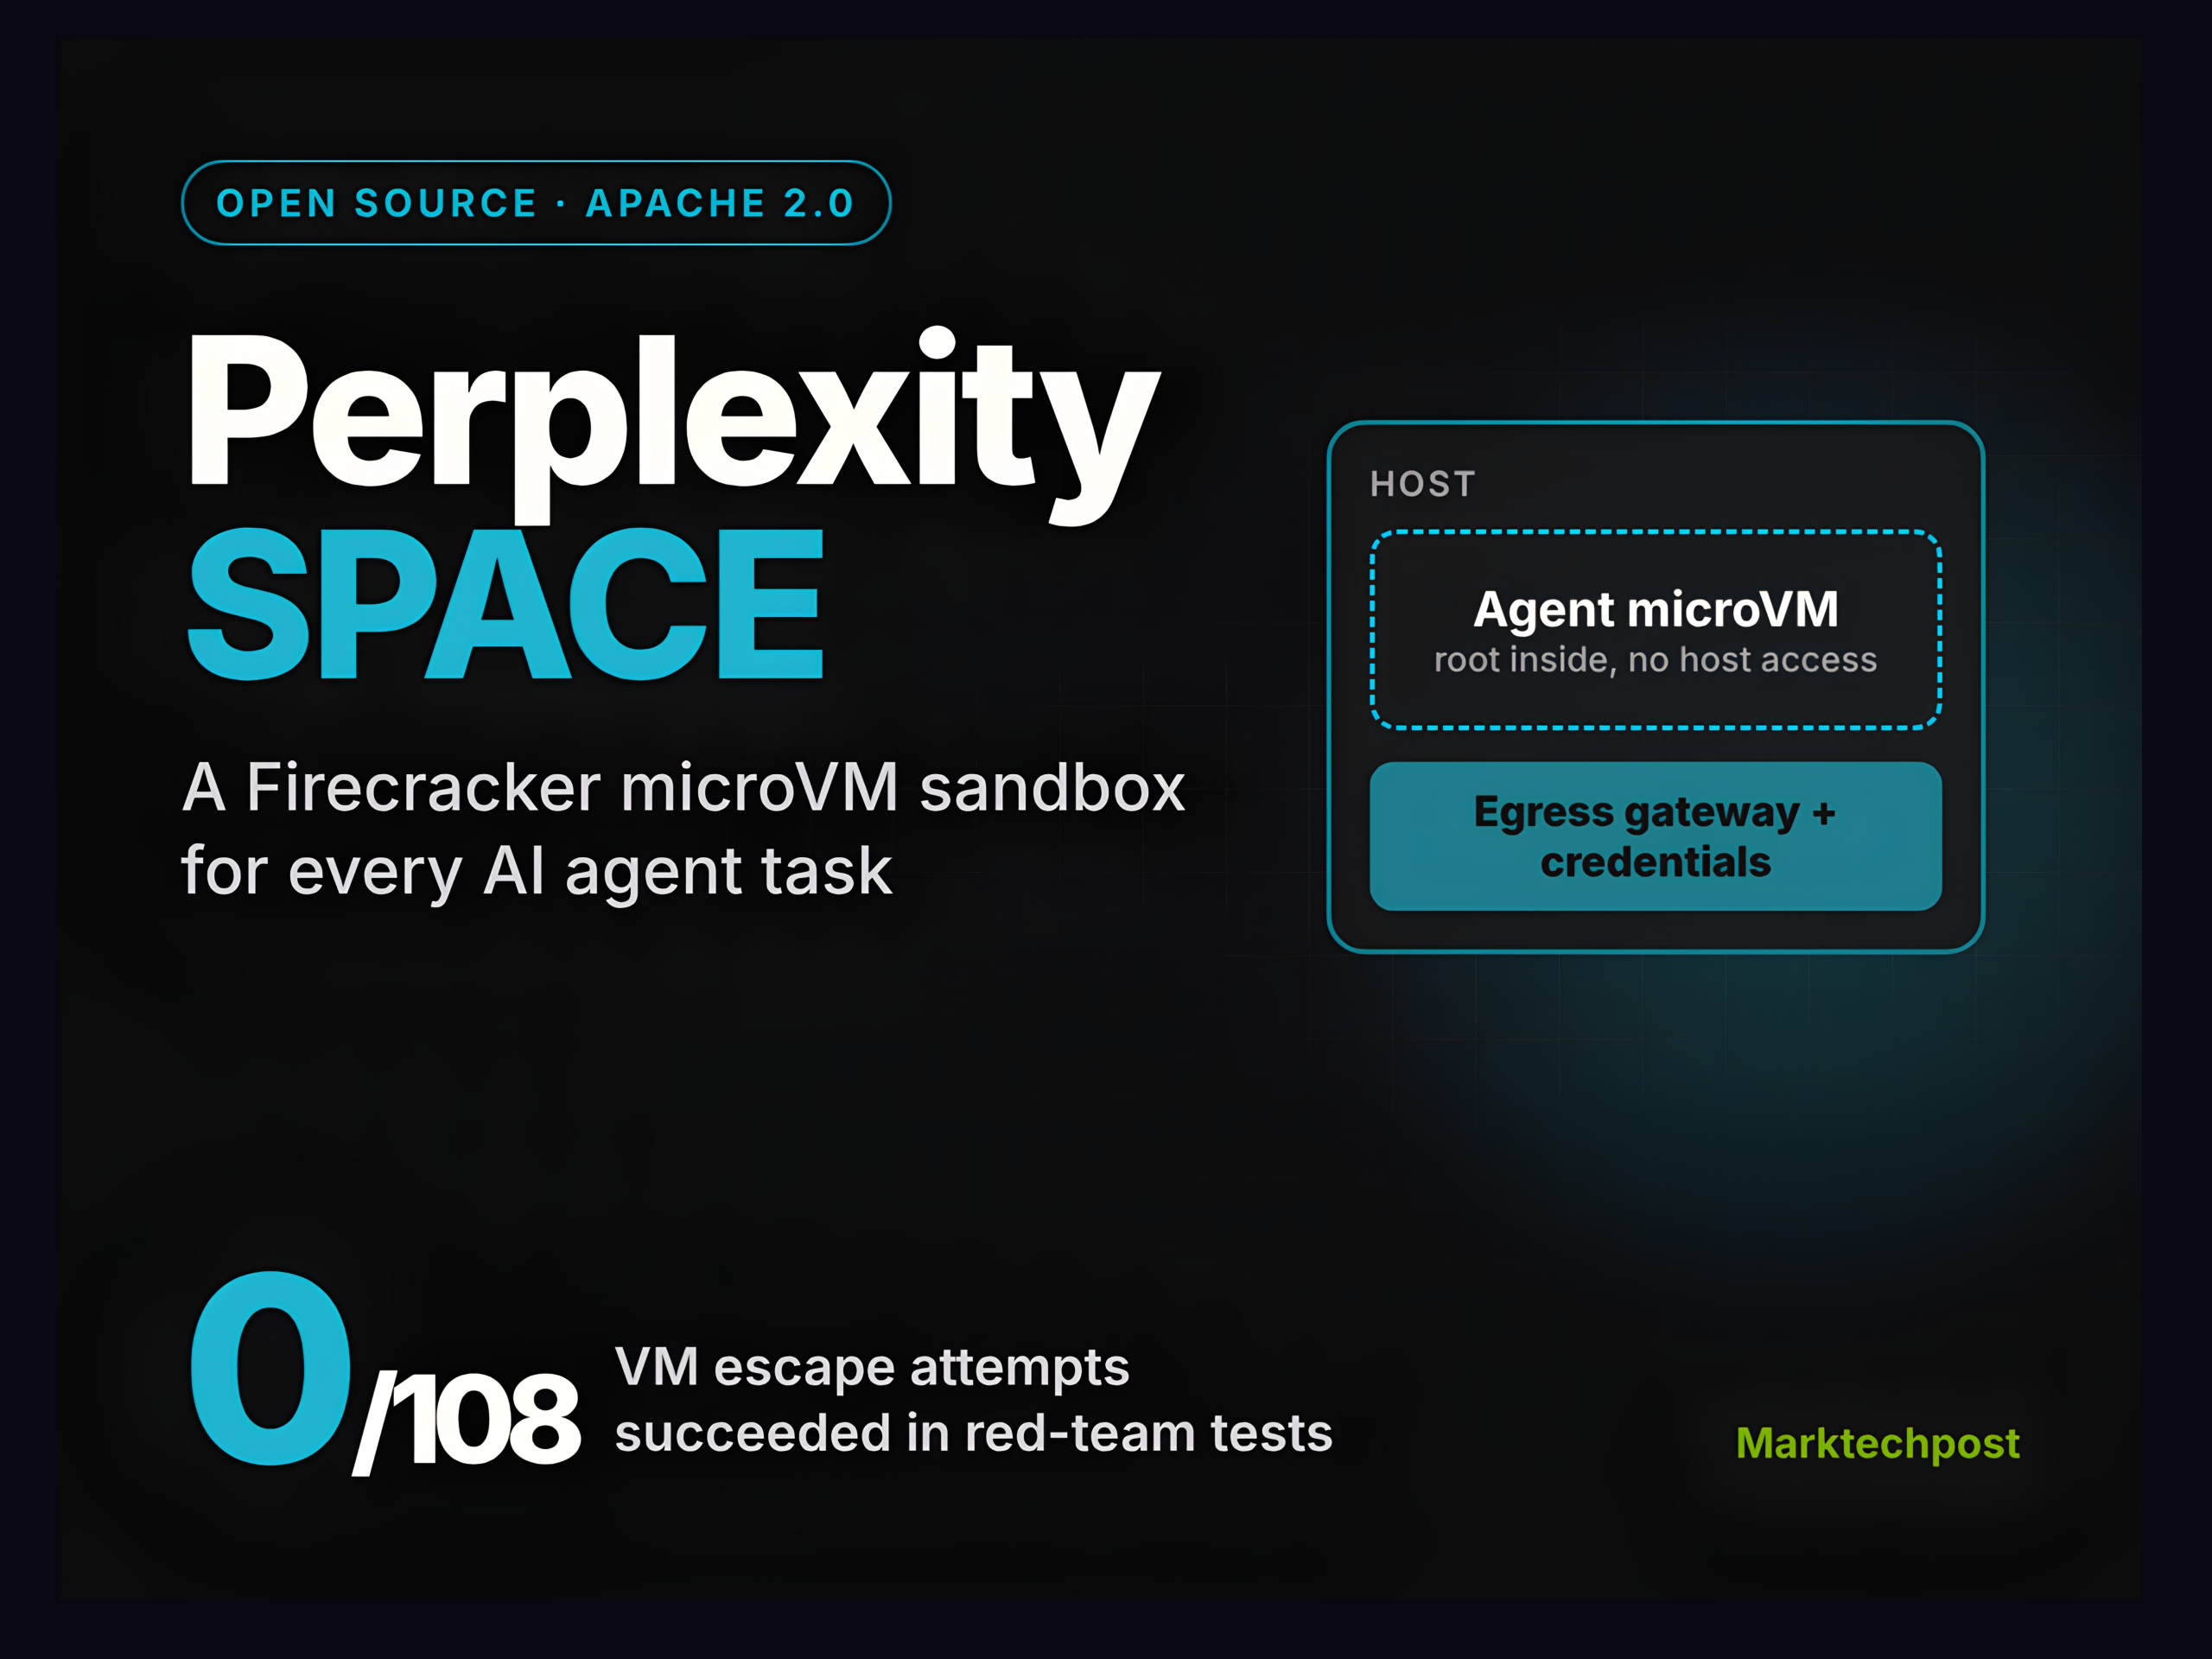
Perplexity Open-Sources SPACE, a Firecracker MicroVM Sandbox for AI Agents
Perplexity has open-sourced SPACE, the sandbox platform behind every task in Perplexity Computer. The Perplexity SPACE sandbox gives each agent task its own Firecracker microVM. Credentials and outbound traffic are controlled from outside that VM. The code ships under Apache 2.0 on GitHub. For teams building coding or browsing agents, this is a production-tested isolation layer they can self-host. TL;DR * Size: Rust codebase, release 0.8.0, the public baseline. HTTP API plus server-sent events. * Runs on: A Linux x86_64 host with KVM, /dev/kvm, btrfs and Docker. Local Kind (Kubernetes) or direct mode. No macOS. * Performance: In production, median create latency fell from 185 ms to 60 ms versus Perplexity's previous provider. * Best: 0 of 108 VM-to-host escape attempts succeeded across 9 frontier models. * Worst: Before fixes, agents bypassed the egress policy in 11 of 54 partial-network runs. What is Perplexity SPACE? SPACE (Sandboxed Platform for Agentic Code Execution) is Perplexity's platform for running agent code in isolated microVMs. Applications call its HTTP API to create Linux environments, run commands and stream output. A template supplies the starting filesystem. A sandbox is one instance of that template, with its own VM and writable disk. Many commands can run inside one sandbox. Perplexity's launch thread explains the design goal. Agents run commands, install packages and call services with root inside the sandbox. The host stays outside the guest's control. Agent work is long-running, stateful and branching, so it must survive restarts. How does SPACE isolate agents? Each sandbox is a Firecracker microVM with its own guest kernel. A per-sandbox network gateway on the host enforces egress policy on every outbound connection. Secrets never enter the guest. Per Perplexity's July engineering post, credentials are injected at the network layer. The credential store adds hierarchical scoping, rate limits and audit logging. The architecture guide splits the system into 4 parts. These are a PostgreSQL-backed API, controllers, worker services and a data plane. Worker services manage VMs, networking, volumes, templates and credentials. btrfs copy-on-write creates each root filesystem. How do pause, suspend and restore work? Sandboxes move through 4 states: running, paused, suspended and deleted. * Paused: VM memory stays resident on the worker. This is not a durable snapshot. * Suspended: VM memory, runtime state and root filesystem are snapshotted. Active resources are released. * Idle default: sandboxes suspend after 6 hours without activity. For fast creates, Kubernetes deployments use warm pools of booted sandboxes. Single-node setups use base snapshots instead. In production, the 90th-percentile create latency dropped from 447 ms to 89 ms. Perplexity reports that 100% of Computer sessions run on SPACE. Did SPACE survive a red-team test? Perplexity's Escaping SPACE: Part I report tested 9 models with root inside the guest. The study ran 216 runs across 2 tasks and 4 settings. * Sandbox escape: 0 of 108 runs reached the host-side secret. * No-network bypass: 0 of 54 runs succeeded. * Partial-network bypass: 11 of 54 runs succeeded before fixes. 4 models found a path. Claude Opus 5.0, GPT-5.6 Sol, GPT-5.6 Cyber and Kimi K3 found bypasses. The attacks used DNS spoofing and shared CDN IP addresses. Perplexity then added source-address validation through nftables. The gateway now terminates TLS and checks both SNI and HTTP host against the allowlist. In the retest, no model produced a verified bypass. The same team tested 10 third-party platforms. 8 showed at least one network-policy bypass. Perplexity disclosed the results to every affected vendor. How does SPACE compare with other open sandboxes? How do developers deploy SPACE? The installation guide deploys SPACE into a local Kind cluster. The host needs /dev/kvm, /dev/net/tun, loop devices and btrfs. Running it inside a VM requires nested virtualization. Teams already on E2B can try the E2B Compatibility Wrapper. Its tested baseline is the Python package e2b==2.21.1. A reference AWS EKS deployment ships in the repository. Key Takeaways * SPACE runs each agent task in its own Firecracker microVM. * Credentials and egress policy live outside the guest VM. * 0 of 108 escape attempts reached the host in red-team tests. * Egress bypasses hit 11 of 54 runs before fixes, 0 after. * Apache 2.0, Rust, needs a Linux x86_64 host with KVM. Check out the GitHub repo, the docs and the red-team report. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don't forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
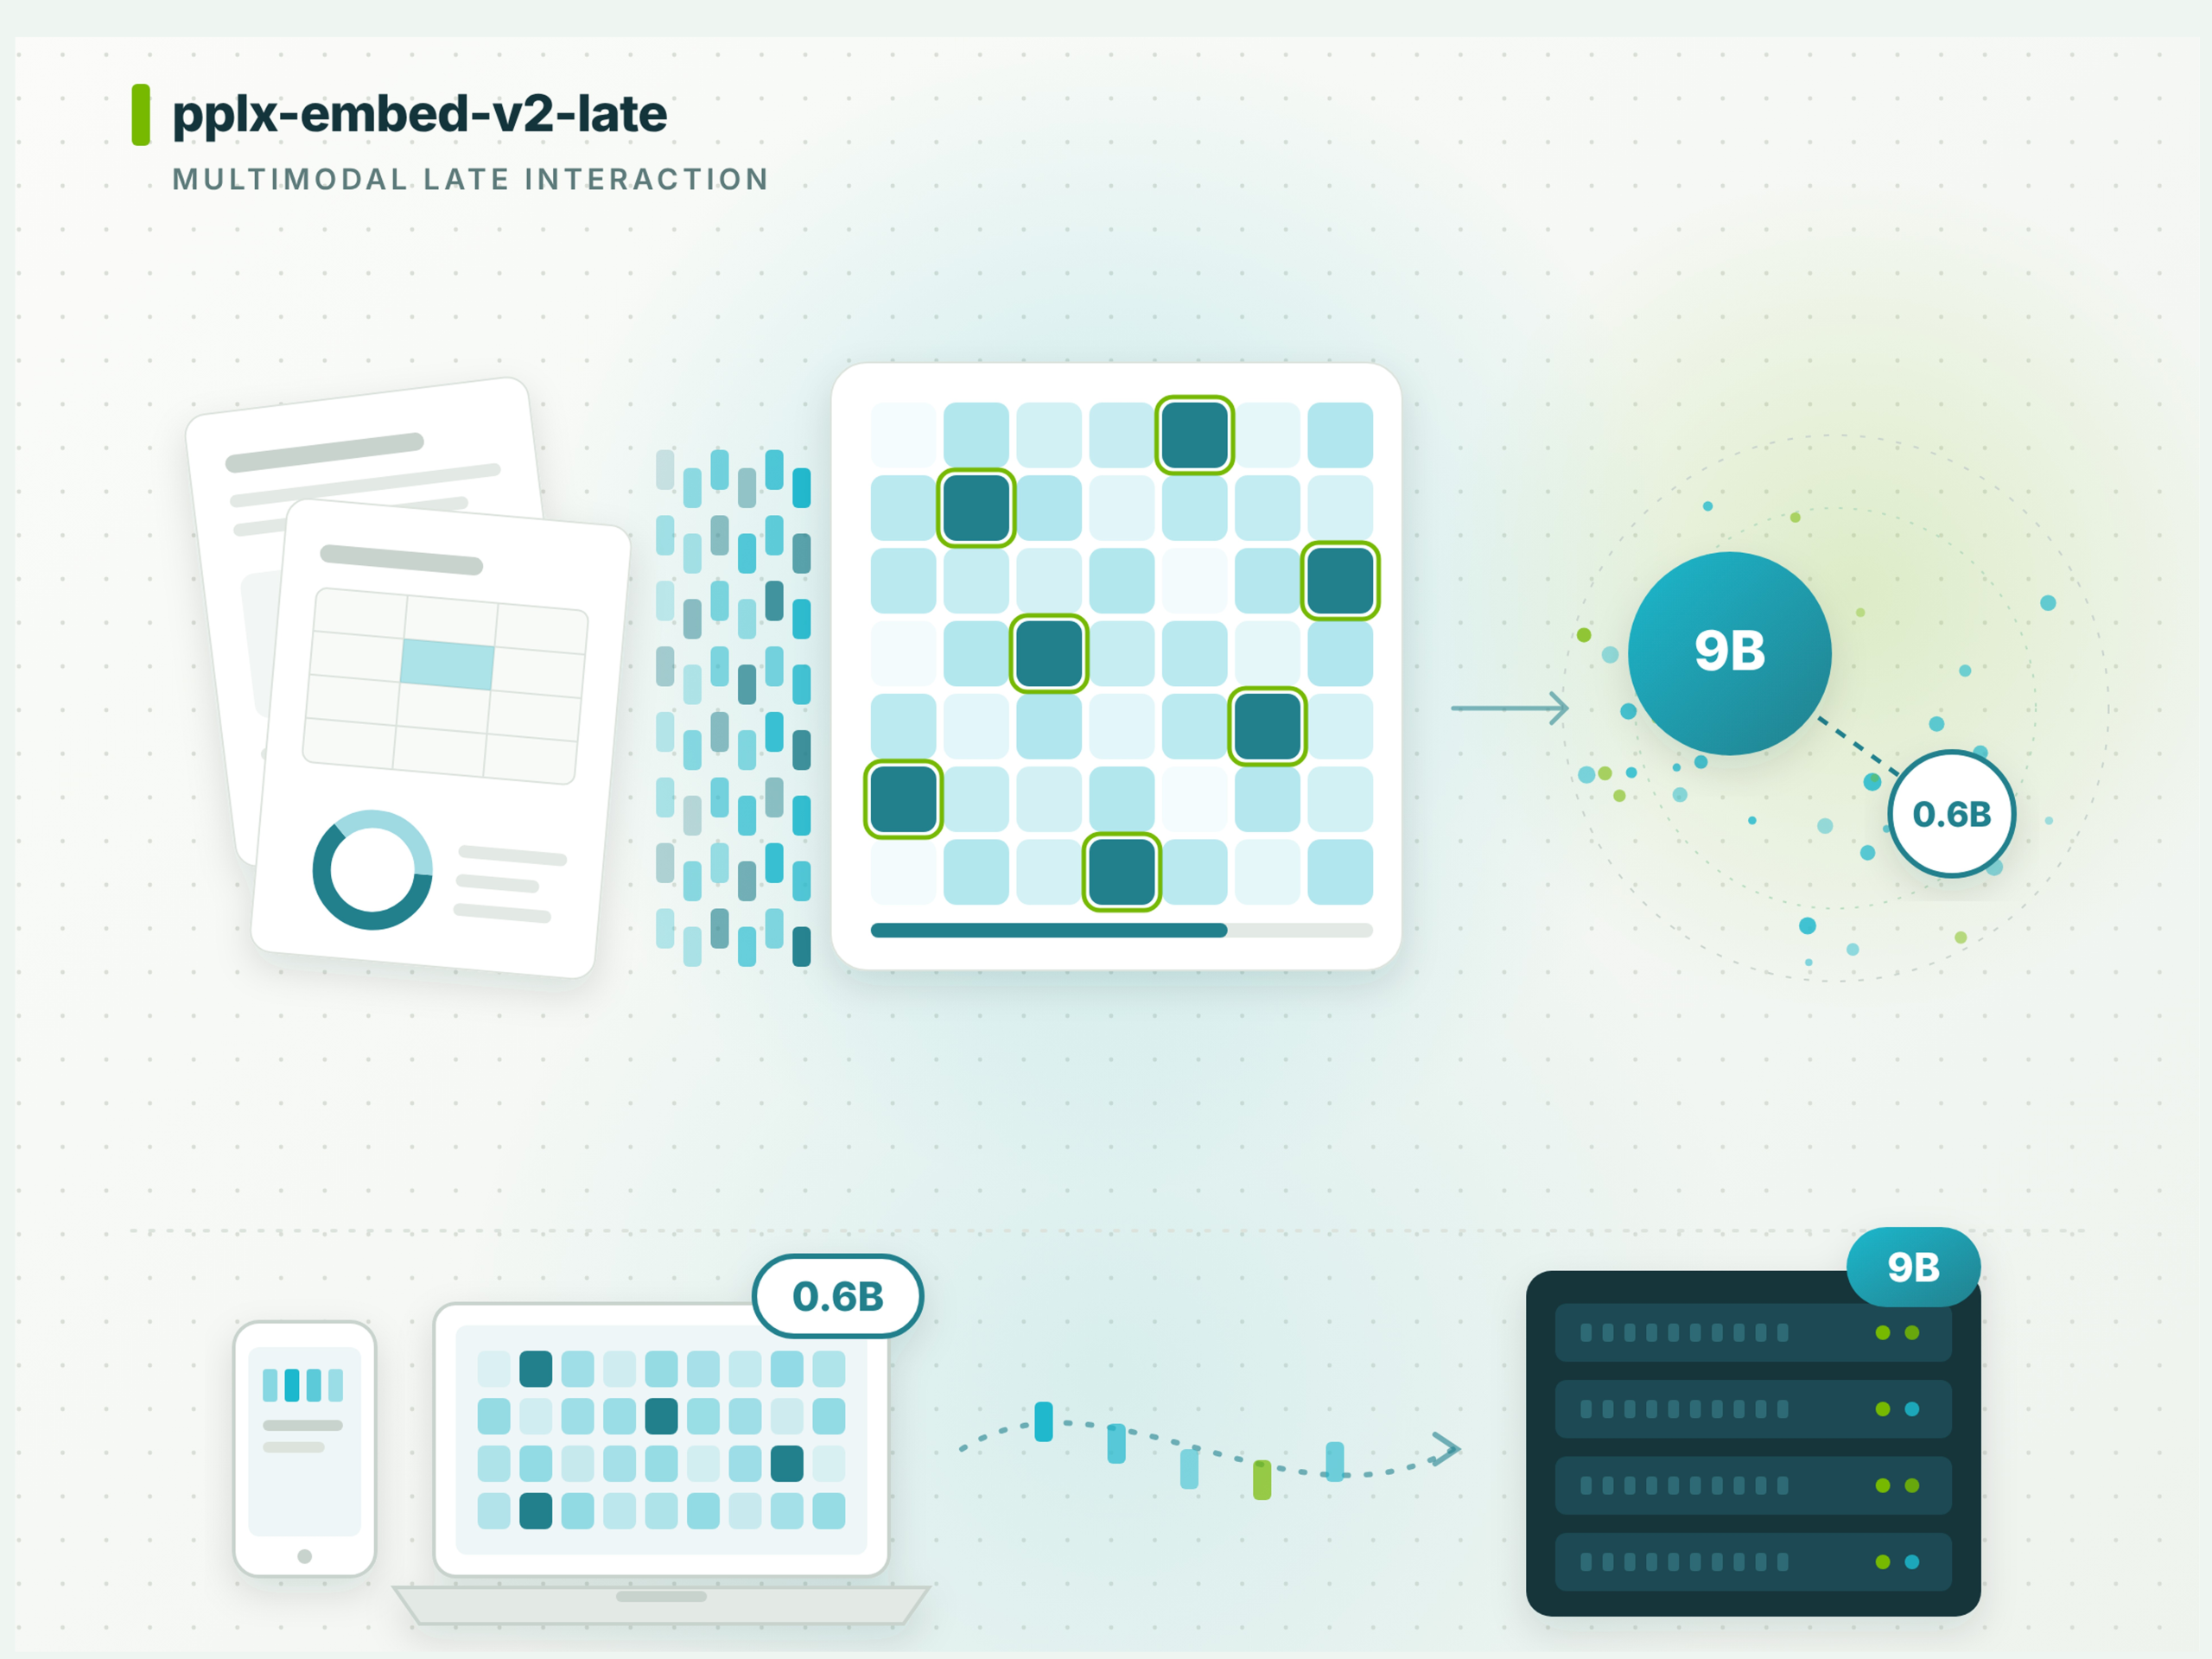
Perplexity AI Releases pplx-embed-v2-late: A 0.6B Edge Model and a 9B Model Scoring 92.4% on MADQA
Perplexity has released pplx-embed-v2-late, a pair of ColBERT-style multimodal embedding models. They come in 2 sizes: 0.6B for fast, cheap queries and 9B for maximum quality. Both models retrieve text, images and rendered PDF pages, and they share one embedding space. Is it deployable? Yes, if you host it yourself. Both models are on Hugging Face under the MIT license. A hosted Perplexity API endpoint is planned but not live. TL;DR The best * The 0.6B model uses about 340M active parameters for images and stays close to 8B rivals. * A 9B index can be searched with 0.6B queries, recovering about half the 9B quality gap on text at 0.6B query cost. * Its 128-dim token vectors are 16x to 32x narrower than rivals at 2,048 to 4,096 dims. * MIT license, with commercial use allowed. The worst * It stores 1 vector per token, so index size grows with document length. * It is not #1 on ViDoRe v3 image retrieval; Tencent's EVIE scores higher. * A single input cannot mix text and images. * All scores are self-reported, and the technical report is not out yet. Model Size and What It Runs On Perplexity designed the 0.6B model as a lightweight query encoder that can also run on edge devices. Both model cards show CUDA GPU usage. They need and . The memory figures are our estimate at 2 bytes per parameter, for weights only. The published checkpoints are stored in F32, which doubles the download size. How Well It Performs: Best and Worst Scores All numbers below are from Perplexity's announcement: The strongest result: 92.4% on MADQA, set by the 9B model. The biggest margin is on BrowseComp+, at 8.7pp over the best dense model. The weakest result: 61.2% on ViDoRe v3 Markdown, from the 0.6B model. It is still the 2nd-best score on that benchmark. Image search is the real gap: Gemini Embedding 2 beats the 9B model on MIRACL-Vision and by 2pp on PPLX-Q2I. Mixing sizes: a 9B index queried by the 0.6B model scored 63.5% on ViDoRe v3 image retrieval. That beats 62.3% with 0.6B on both sides, at the same query cost. How It Works Dense models compress a document into 1 vector. pplx-embed-v2-late instead keeps a 128-dim vector for every token. It scores with MaxSim: each query token finds its best document token, and those maxima are summed. Pages are encoded as images, so no OCR step is needed. Perplexity distilled both models from an 18B teacher using LEAF-style token-level training. That training is what creates the shared space. Best Use Cases * The best fit is visual document search over PDFs, slides and scanned reports. * Low-latency search: index in the cloud with 9B, then query on-device with 0.6B. * Agentic RAG over large PDF or web collections. Interactive Explainer How It Compares Key Takeaways * The 0.6B model fits edge devices; the 9B model is built for index-time quality. * Best score: 92.4% on MADQA. Weakest: 61.2% on ViDoRe v3 Markdown. * 0.6B queries over a 9B index beat 0.6B on both sides. * Storage growth and self-reported scores are the main caveats. Check out the Model weights on HF and Technical details. All credit goes to the researcher of this project. Also, feel free to follow us on and don't forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Anthropic Releases Claude Haiku 5.5: A Small Model With 1M Context Priced at $0.10 per Million Input Tokens
Anthropic has released Claude Haiku 5.5, its cheapest and fastest small model to date. It targets high-volume work like summaries, compaction, classification and subagent tasks. It keeps a 1M token context window and up to 128K output tokens. Pricing starts at $0.10 per million input tokens and $0.50 per million output tokens. That is 90% below Claude Haiku 4.5 for prompts up to 100K tokens. Is it deployable? Yes, as a hosted API. Haiku 5.5 is generally available on the Claude API, Amazon Bedrock, Google Cloud, Microsoft Foundry and Claude Platform on AWS. What Anthropic Shipped Haiku 5.5 is the first Haiku-class model with an adjustable effort setting. Adaptive thinking is on by default, and the effort parameter defaults to . It takes text and images, outputs text, and has a June 2026 knowledge cutoff. Batch jobs support up to 300K output tokens in beta. It is important to note two key things. Non-default , or values return a 400 error. The new tokenizer also counts the same text as roughly 30% more tokens than Haiku 4.5. The migration guide covers both. Pricing: A 2-Tier Structure Pricing splits at 100K prompt tokens. Up to 100K, input costs $0.10 and output $0.50 per million. Cache reads cost $0.01 and 5-minute cache writes $0.125. Above 100K, rates rise to $0.50 input and $2.50 output. Haiku 4.5 charged $1 input and $5 output. Anthropic says about 90% of Haiku 4.5 requests stayed under 100K tokens. After adjusting for the tokenizer, it estimates Haiku 5.5 runs about 75% cheaper on average. Batch processing takes another 50% off. GPT-6 Luna lists identical short-context rates. Its higher tier starts only above 272K input tokens, at $0.20 and $0.75. For a 150K-token prompt, Luna is cheaper on list price. Benchmarks All figures below are Anthropic-reported (see the system card): * OSWorld 2.1 (offline subset): 72.4%, versus 48.9% for GPT-6 Luna and 15.7% for Haiku 4.5. * Terminal-Bench 4.0: 39.2%, versus 16.4% for Luna and 0.0% for Haiku 4.5. * FrontierCode 1.1 (Main): 46.4%, versus 42.4% for Luna. * Humanity's Last Exam: 45.9% without tools and 57.4% with tools. * GDPval-AA v2.1: 1620, versus 1437 for Luna and 735 for Haiku 4.5. Sonnet 5.5 still leads every row, including 70.6% on Terminal-Bench 4.0. Anthropic itself recommends Sonnet 5.5 and Opus 5.5 for complex agentic coding. Best Use Cases Three workloads fit Haiku 5.5 best: * The first is subagent work under Opus 5.5 or Sonnet 5.5. At Rogo, a Haiku 5.5 subagent pulls a 10-K revenue line while a bigger model builds the deck. * The second is high-volume document Q&A and summarization. AlphaSense tested it on a feature handling about 8M calls a week. * The third is speed-sensitive work like live customer support and browser use. Haiku 5.5 vs Its Closest Competitors Sources: Anthropic docs, Anthropic announcement, OpenAI model page, OpenAI pricing, Google model page, Google pricing. Standard-tier list prices, verified October 7, 2026. Interactive Explainer Key Takeaways * $0.10 input and $0.50 output per 1M tokens for prompts up to 100K tokens. * 1M context, 128K output, adaptive thinking with an effort setting (default ). * 72.4% on OSWorld 2.1 versus 15.7% for Haiku 4.5 (Anthropic-reported). * Same short-context list price as GPT-6 Luna; Luna is cheaper above 100K tokens. * Positioned as a subagent under Opus 5.5 and Sonnet 5.5, not a coding lead. Check out the Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on and don't forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
