News & Updates
The latest news and updates from companies in the WLTH portfolio.
Tens of thousands of Nvidia GPUs sit in Meta's Prometheus supercluster, waiting for a failure
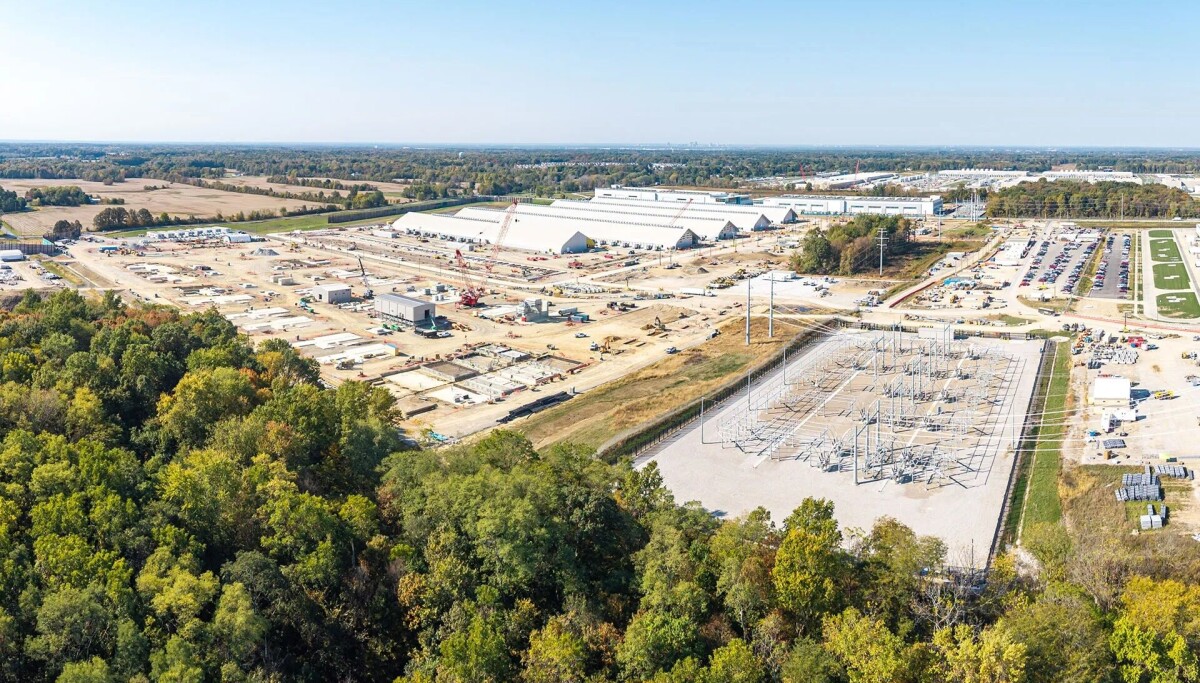
And other fun facts about how Zuckercorp aims to keep a million GPUs running long enough to train a model More than 11 percent of the GPUs at Meta's Prometheus supercluster in New Albany, Ohio, are either dead or sitting idle waiting to step in when the next drops out, Zuckercorp revealed this week. The massive pool of redundant GPUs is just one of several measures the hyperscaler has taken to keep its AI training runs on track. Prometheus is among Meta's largest compute deployments to date. Powered by Nvidia's Grace Blackwell and (soon) Vera Rubin rack systems, Meta says the supercluster will eventually scale to a gigawatt of capacity spanning about a million accelerators. But as anyone who has worked on a large scale compute cluster understands, whether for LLM training or traditional HPC workloads, more chips inevitably means more problems. In an eight-GPU node, the chance of having a GPU fail is relatively low. In a 100,000-GPU cluster, failures are unavoidable. Meta is building something that's 10x larger and requires distributed training runs across multiple datacenters. Keeping the entire thing humming long enough to reach the next checkpoint becomes a major headache. In a blog post published this week, Meta offered a unique look at the work it's done to keep failures from derailing the development of models like Muse Spark or its most recent release Muse Wonder. Idle GPUs are the cost of continuity When Meta began the first phase of its Prometheus deployment in New Albany, the company says, it was experiencing roughly 1,000 interruptions per day for every 8,000 GPUs. Interruptions don't mean GPU failure. They simply mean something crashed, failed, or timed out, forcing the training run to stop and roll back to the last known good checkpoint. Meta claims in the year since it's been able to cut down the number of interruptions by 99 percent, to about 11 per day per 8,000 GPUs. One of the ways it's done this is by keeping some of Prometheus' GPUs in reserve. The cluster is currently powered by a combination of GB200 and GB300 systems, each with 72 GPUs per NVLink domain. However, only 64 of them are ever in use at any given moment. The other eight are essentially hot spares. Meta tells us that while these spare GPUs may not be used in the larger training run, they are still available to run opportunistic side jobs, which can be preempted in the case of a failure. Meta did this because a single failed GPU would take out an entire rack and interrupt the training run. Now, when a GPU fails, one of the spares can slot in and take its place. While this saves time -- Meta doesn't have to drop the entire rack from the cluster or wait for someone to swap the faulty component to start training again -- a failed GPU would still result in an interruption, albeit a shorter one. Parallel resiliency To mitigate this, Meta took advantage of the fact that large scale training jobs usually use data parallelism, where multiple copies of the model are resident within the cluster. "When a fault can be isolated to a data-parallel model replica, we reduce the impact of a hardware failure by allowing a single faulty replica to be taken offline, while the remaining cluster repeats that step and continues productive training," Meta explained. "The compromised slice simply restarts on available spare hosts and resynchronizes, converting a potential total system halt into a minor, temporary reduction in aggregate throughput." In other words, Meta's training runs only get interrupted if the fault exceeds the data parallel domain. When this happens, the company has implemented a comprehensive checkpointing scheme, which you can think of a bit like auto-save or a revision history. That way if something does fail, Meta doesn't have to start over from scratch. "Our distributed checkpointing architecture asynchronously saves the model state -- including gradients and optimizer data -- to multi-tier storage," the company wrote. NVLink growing pains Meta says one of the most difficult challenges was making the NVLink fabrics used to connect 72 GPUs behave like one great big accelerator. Earlier H100 and H200-based systems featured just eight GPUs per NVLink domain, which meant the links were far shorter and less numerous. But this functionality was expanded nine-fold with Nvidia's Blackwell generation. "With over 600,000 NVLink connections, even marginal signal degradation triggers frequent NVLink recovery cycles," the company wrote. To overcome this, Meta had to implement a continuous telemetry system and conduct L11 diagnostic burns to isolate weak links before the systems were put into production. Power was another challenge. Ramping up and down tens of thousands of GPUs for a training run can introduce massive spikes in power consumption called transients, which can overwhelm power supply equipment. According to Meta, by focusing on the stability and reliability of its cluster, it was able to achieve more than 85 percent "goodput" -- a measure of useful throughput -- for pretraining and more than 90 percent for reinforcement learning on its latest model Muse Wonder. The company's ambitions don't stop here. As it works its way toward a million GPUs, Meta hopes to get its interruption rate down to just two per day for every 8,000 GPUs, or about 100,000 GPU-hours mean time between interrupts. ® Update: Following publication, Meta reached out to clarify that spare compute is used to run opportunistic jobs that cane be preempted in case of a failure. We have updated our story and the headline to reflect this.
Canonical Observability Stack: Reimagining observability with MicroK8s and Grafana, Prometheus and Grafana Loki | Ubuntu
Note: This post is co-authored by Jon Seager. Jon Seager is the Vice President of Enterprise Engineering at Canonical with responsibility for Juju, the Charmed Operator Framework, and several charmed operator development teams which operate across different software flavors, including observability, data platform, MLOps, identity, and more. Juju re-imagines the world of operating software securely, reliably, and at scale. Juju realizes the promise of model-driven operations. Excellent observability is undeniably a key ingredient for operating software well, which is why the Charmed Operator ecosystem has long provided operators the ability to run a variety of open-source monitoring software. We collectively refer to these operators as the Logs, Metrics, and Alerts (LMA) stack. With the advent of cloud-native software and microservices, and the resulting increase in the complexity of systems, we decided it was time to create the next generation of LMA running on Kubernetes. It needed to be capable of monitoring workloads running on Kubernetes, virtual machines, bare metal, or the edge. Going back to the drawing board, we also reassessed which components would be part of this new cloud-native observability stack. The resulting design comprises open-source projects led or heavily contributed to by Grafana Labs. Let us tell you why. There's something about Juju ... Juju takes a fundamentally different approach to building and operating infrastructure. Rather than focusing on low-level components, such as virtual machines, subnets, or containers, Juju focuses the user on operating applications while it takes care of the rest. At the heart of any Juju deployment lies a controller, which is aware of a set of underlying clouds and the state of the models and applications it's managing. Models in Juju are essentially workspaces for groups of related applications, and applications are known as Charmed Operators. A Charmed Operator comprises code that understands how to install, configure, integrate, and generally operate a piece of software. It uses an agent to communicate with the Juju controller, which is provisioned automatically when you deploy an application. Juju's advantage is that Charmed Operators function the same whether your underlying cloud is AWS, Azure, OpenStack, VMware, Kubernetes, and more. You're always just one juju deploy foo away from competently operating software with Juju, where the user experience and tooling are consistent across clouds and enable seamless integration between them. There is an ever-growing collection of Charmed Operators available on Charmhub. Go have a look! A new LMA for the new cloud-native world The new LMA stack, which we call the Canonical Observability Stack (or COS for short), has the following design goals: * Quality and reliability: Uptime and reliability are a must for any software, but much more so for your monitoring software. If your monitoring software is not up and running to tell you what else is not working, what good is it? * Scalability: Monitoring has a strong network effect. So, with adequate resources, COS should be able to scale to monitor a lot of software for your ops teams, allowing them to have the deepest possible insight into your infrastructure and applications. * Resource efficiency: COS should be able to run at the edge and data centers alike, requiring as few compute resources as possible to fulfill its mission. * Composability: COS should consist of a set of high-quality Charmed Operators that are designed to work well on their own and better together. * Cohesive user experience: COS should ensure a consistent, cohesive experience for end users, with tools that feel designed to work together -- one UI to visualize all types of telemetry. COS should also create consistent metadata on telemetry so that the context of the telemetry ("where is it coming from?") can be used to bridge across telemetry type silos -- from metrics to logs, from logs to alerts -- all while leveraging the same metadata everywhere. * Consistent operator experience: Various pieces of software following a similar philosophy feel similar in terms of operations, failure modes, dependencies, and pitfalls. This consistency helps immensely with reducing cognitive load on the operators. * Monitoring coverage: While starting with logs, metrics, and alerts (that's literally what the "LMA" moniker is made of, after all), there are other types of telemetry that are invaluable in cloud-native environments, such as distributed tracing and synthetic monitoring. COS should be designed with extensibility in mind, so it can grow the capability to process additional types of telemetry. On the flip side, a lot of software is not cloud-native or even running on a cloud. COS should be capable of monitoring software well outside the boundaries of Kubernetes. For example, just focusing on Canonical products, COS should be able to monitor Ceph, Charmed OpenStack, running bare-metal with MAAS or in containers or virtual machines on LXD. * Ease of operations: We want COS to be a monitoring stack that feels like an appliance, with as few knobs to turn as possible, providing great functionality out of the box. We want to entirely remove the toil from setting up the monitoring of your Juju workloads; it should be as simple as establishing a couple of Juju relations. * Showcase the declarative power of the Juju model: If some functionality or integration can be adequately modeled as a relation between Charmed Operators, it should be. Also, relations must be semantically meaningful: By looking at a Juju model, you should intuitively understand what results from two charms being related. The design goals above are ambitious, and we are delighted with how the result of our efforts are shaping up! Our success is thanks in no small part to the amazing quality of the Prometheus, Grafana, and Grafana Loki projects, and how well their philosophy aligns with the design goals for COS, so let's dive deeper into that. Grafana, Prometheus, Alertmanager, Loki to the rescue At Canonical, open source is a part of our DNA. Juju and the entire Charmed Operator ecosystem is open source. We see eye-to-eye on this with the Grafana folks, who are excellent open-source citizens, very responsive to the community, and a pleasure to work with. Many good reasons to build on the Grafana ecosystem But, of course, not only must the people be nice, the software must be nice, too! The open-source projects led and contributed to by Grafana Labs don't disappoint! Put very succinctly, the reasons why we decided to build COS by composing Grafana projects are the following (not necessarily in order of importance!): * Open source software done right. * Easy-to-integrate components. * Resource efficiency. * Shared backing components. * The straightforward nature of how object storage is used. * Consistent philosophy and UX (down to "Loki is Prometheus for logs"). * Good performance and scalability. * Coverage of telemetry types (metrics, logs, distributed tracing, synthetic monitoring, etc.) * Good agent story with Grafana agent: it packs a punch! To expand on the above, Prometheus, Alertmanager, and Grafana have been staples of the previous iteration, and relying on them again in COS was simply a no-brainer: familiarity for end users, quality, ease of use, consistency in design philosophy, resource efficiency -- it's all there! Grafana Loki: a refreshing take on log analytics Loki, the "Prometheus for logs," has displaced Graylog as the log analytics component of choice in COS. We ran a detailed evaluation involving, among other aspects, ease of operations, ease of integration with the other COS components, sparsity of dependencies, and scalability. We got really excited seeing that Loki 2.0 did away with a dedicated index store, further reducing the footprint for COS. Moreover, Loki uses object storage rather than complex databases, which is amazing for reliability and ease of operations. In terms of consistent user experience, Loki is very well integrated in Grafana, and LogQL feels very familiar to Prometheus users. Grafana Agent: a telemetry collection powerhouse Grafana Agent also deserves a loving mention. Monitoring benefits greatly from the network effect: the more you monitor together, the easier it is to find correlations and root causes. The ease of enabling telemetry collection helps to achieve this network effect: a single agent, capable of collecting and forwarding metrics, logs, and distributed traces goes a long way to reduce the cost and complexity of rolling our monitoring to many systems. We like the Grafana Agent so much that we will build the self-monitoring capabilities of COS with it! We foresee two modes for self-monitoring: one in which the data goes to a remote COS stack (think of it like Prometheus federation, but for the whole stack), and one in which the stack monitors itself, to be used for self-contained deployments. A picture is worth a thousand words The declarative nature of Juju lends itself really well to graphical representations. Here above you see a diagram representing the deployment of an COS in a Juju model and how the various Charmed Operators interact with one another. (Note that not everything in the diagram is implemented just yet.) As mentioned before, the self-monitoring of the stack by the Grafana Agent is something we look forward to implementing soon. Similarly, we are working on charming (what the Juju community calls the process of creating a Charmed Operator) an Ingress controller so that we can expose outside various endpoints that are needed to monitor or receive data from outside the MicroK8s cluster since that, for resilience reasons, we want COS to be hosted in a dedicated MicroK8s cluster and share as little infrastructure as possible with the workloads it monitors. The endpoints that will need to be exposed outside of the MicroK8s cluster are: * Loki push_api endpoint * Web UIs of Prometheus, Alertmanager and Grafana * Prometheus's remote_write endpoint (Note: We currently do not plan to implement support for Prometheus federation or remote_read, but if the use-case arises...) And this is just the beginning With regard to telemetry types, the work on the new cloud-native COS is currently focusing on metrics, logs, and alerts. But there is more than that to observability, especially in cloud-native environments. On the "What is observability?" page, we go through a number of other telemetry types, like distributed tracing, or end-user and synthetic monitoring. The Grafana ecosystem has projects, such as Grafana Tempo and k6, that fit those bills, which makes us confident that as COS grows and becomes more capable, it will be able to leverage projects with this consistent philosophy and quality as it does today with Prometheus, Grafana, and Loki. Another direction we want to pursue with COS is high scalability and availability. We are looking with great interest at Cortex as a way of bringing multi-tenancy and resilience to the Prometheus experience, and Loki already has many of the capabilities we need in that dimension. Join us in making model-driven observability a first-class experience on the Charmhub Mattermost, have a look at the COS documentation, or jump right into it and take LMA Light for a spin!

Meta Unveils Muse Wonder Models to Challenge OpenAI and Anthropic in Frontier AI Race
Meta has released two new artificial intelligence models, Muse Wonder and Muse Wonder Full, marking its first attempt to compete directly with leading frontier models from OpenAI and Anthropic as the company intensifies its push into more capable AI systems and personal assistants. The models, unveiled on Monday by Meta's Superintelligence Lab, represent a significant step beyond Muse Spark, the company's earlier lightweight model designed to deliver responses with low latency. Meta says the new models are larger, achieve higher benchmark scores, and perform better on complex tasks, including coding. According to testing results presented in Meta's model card, Muse Wonder and Muse Wonder Full achieve benchmark performance comparable to Fable 5.1 and GPT-6 Astra. The company described the release as part of a broader effort to scale its AI capabilities toward more personalized systems that can understand users and assist them over extended periods. "Together, they mark the next step on our scaling ladder and a major leap toward personal superintelligence," Meta said in its blog post announcing the models. The launch signals a change in emphasis for Meta's AI strategy. After introducing Muse Spark and the Muse agent, the company is now moving towards more powerful models designed to compete on capability rather than relying primarily on lightweight systems and fast inference. The increased scale of the Wonder models is reflected in their pricing. Through Meta's Model API, Muse Wonder will cost $4 per million input tokens and $20 per million output tokens, placing it at roughly the same price level as GPT-6 Sol and Opus 5.5. The pricing positions Muse Wonder as a more expensive offering than a model designed mainly for lightweight, low-latency interactions. For developers and businesses, the commercial question will be whether its performance on demanding tasks justifies the additional inference costs. Muse Wonder Full, meanwhile, will be available exclusively to Muse Code subscribers and will not be offered through the API. Meta has not made the model broadly accessible to developers through the same channel as Wonder, limiting its availability to users within the company's coding product. Both models will also power the Muse agent, Meta's system for carrying out tasks on behalf of users. Integrating the models into that product gives Meta a way to deploy their capabilities in a consumer-facing assistant rather than treating them solely as standalone models for developers. AI companies are increasingly competing to build systems that can do more than answer individual prompts. More capable models can potentially support longer workflows, complex coding assignments, and tasks requiring information to be retained across multiple interactions. However, stronger benchmark results alone do not establish how reliably a model will perform in everyday use or whether its capabilities will translate into sustainable commercial returns. Meta Puts Memory At The Centre of Its AI Ambitions One of the defining features Meta emphasized in the launch is what it calls "active memory": the ability of a model to retain, retrieve and synthesize information supplied by a user over time. The company is positioning this capability as an important component of personal AI assistants, which may need to remember preferences, ongoing projects and previous instructions across days, weeks or months. Better memory could reduce the need for users to repeatedly explain their circumstances and allow an assistant to provide more consistent support across extended tasks. Meta highlighted MemoryBench, a benchmark designed to assess continual learning and memory-construction frameworks, as evidence of progress in this area. According to the company's own testing, Muse Wonder scored higher on MemoryBench than Fable, Opus, or Astra. "We put a tremendous amount of effort into making sure your model can remember what's important to you over days, weeks, months and beyond," research scientist Kavya Kopparapu said in a video accompanying the launch. The emphasis on memory suggests that Meta is pursuing a broader definition of AI performance than conventional measures of reasoning, coding or general knowledge. For a personal assistant, the ability to maintain useful context over time could be as important as the ability to solve a difficult problem in a single interaction. But that ambition also creates challenges. A system that retains information over long periods must distinguish useful context from irrelevant details, retrieve the right information when needed, and handle personal data appropriately. The launch announcement highlights Meta's technical focus on memory, but the available benchmark claims do not by themselves establish how the models will perform across all real-world settings. A New Phase in Meta's Frontier-Model Push The release is the first frontier-model launch since Scale AI founder Alexandr Wang restructured Meta's AI operations in August last year. Since that reorganization, Meta has introduced the lightweight Muse Spark model and the Muse agent but has largely avoided the kind of high-profile, state-of-the-art model releases associated with OpenAI and Anthropic. Muse Wonder and Muse Wonder Full therefore provide an early indication of how the restructured organization intends to compete at the upper end of the AI market. Meta's reported benchmark comparisons place the models in the same performance range as selected offerings from its rivals. However, those comparisons are based on the company's own testing, and benchmark parity does not necessarily mean that models are interchangeable across coding, reasoning, agentic workflows, or other applications. The infrastructure behind the launch is also significant. According to Meta, the models were trained at its Prometheus data center in central Ohio, which came online earlier this year. The facility provides part of the computing infrastructure supporting the company's expanding AI development effort. The challenge for Meta now extends beyond producing models with competitive benchmark scores. The company must demonstrate that its larger systems can deliver useful performance in products, sustain adoption among developers and users, and support a credible business model as inference costs rise. The integration of Wonder into the Muse agent offers one route to achieving that goal. If the models can combine strong reasoning and coding capabilities with reliable long-term memory, Meta could strengthen its position in the emerging market for personal AI assistants. The launch does not settle the contest with OpenAI and Anthropic, but it signals that Meta is moving more directly into frontier-model competition.
Who Chained Prometheus to the Electricity Meter? A Question for the Government of Meghalaya
There's a candle stub on the windowsill of nearly every house in Syad Lyngdoh village. Nobody put it there for decoration. It's there because we've learned, the way you learn which step on the stairs is loose, that the light is going to go. Not might. Will. Usually around dinner time, sometimes in the middle of a child's homework, and almost always without a word of explanation from anyone. For years I told myself this was a village problem - Always. Ri-Bhoi gets what's left over, the interior gets what's left of that, and that's how it's been since before I was old enough to complain. But. lately, friends in Shillong tell me the same story from Laitumkhrah, from Mawlai, from Nongthymmai. The fridge stops, starts, stops. The inverter beeps through the night. A tailor loses half a day's orders; a student in a rented room revises for exams by the light of her phone. The capital, it seems, has caught the village's illness. And every month, without fail, the bill arrives. It never loses its way. It never suffers a technical fault. When it rained hard, we blamed the rain, and honestly that was fair. A tree comes down on the line in July, you light the candle, you don't write angry letters. But the heavy rains have eased and the light still goes. The official explanations, meanwhile, keep shifting. In January the Power Minister, Metbah Lyngdoh, told the press, "There is no load shedding in Meghalaya," and said outages came only from repairs and unforeseen faults. By the end of May he was more candid. He admitted to The Shillong Times that shutdowns couldn't be avoided while RDSS and other works went on, offered no date by which they'd end, and asked us to bear the "temporary inconvenience." Months before either statement, MeECL's chairman had told reporters that shutdown notices appear in the newspapers every day. I read the newspapers. I'm still waiting to find Syad Lyngdoh in one of those notices. (Perhaps I've been reading the wrong page.) Here's the part that should make every household in this state sit up. Under the tariff MSERC approved for 2026-27, in force since 1 April, a domestic consumer pays a fixed charge of Rs 90 for every kVA of connected load, every month. That's before a single bulb is switched on. A modest house with a two-kVA connection owes Rs 180 a month whether the wire is live or dead. If the transformer burns out on the 3rd and nobody replaces it till the 19th, the fixed charge doesn't notice. It's billed in full. Gogol understood this arrangement better than our regulators seem to. In his book - Dead Souls, Chichikov travels from estate to estate buying serfs who've died, because on the government's census list they're still alive, and their owners go on paying tax for them until the next count. Paper life, real tax. We've built the modern version: paper supply, real charge. Our connections are alive on MePDCL's ledger and they're billed like it. Whether current actually flows through them is a separate question, and not one the ledger seems to record. Nor is this the first time that the arithmetic has been on the household.. So- When MSERC revised the tariffs in the middle of 2024, the Highland Post reported that the change would be more lenient towards the industry but a burden to the ordinary domestic consumers.. Now look at who actually carries it. A daily-wage family in Syad Lyngdoh doesn't own an inverter. It has no generator, no second connection, no relative in Shillong whose line comes back sooner. What it has is the bill, and a deadline. Section 56 of the Electricity Act lets a licensee cut supply once fifteen clear days' written notice has gone out on an unpaid bill, and MePDCL exercises that power with remarkable diligence. The lineman nobody can find when the transformer's down finds the house quickly enough when a payment's late. The duty, in practice, runs in one direction. Premchand has a story about this, set it among wheat fields rather than power lines. In Sava Ser Gehun a poor peasant called Shankar borrows a little more than a ser of wheat from the village priest to feed a wandering holy man. Shankar forgets the loan. The priest does not. A few years later that handful of grain has grown to a debt no wage could clear, Shankar works it off as a bonded labourer, and when he dies his son inherits the debt he owed. Premchand ends by telling his readers almost angrily that he has not made any of it up. I think of Shankar when I see a neighbour counting out notes for the arrears, then the reconnection fee, then next month's fixed charge on a line that sat dead for a week. And where does that neighbour complain? The sub-divisional office, where the phone rings out. The consumer grievance forum, which most people here have never heard of, let alone found. Dostoevsky's Marmeladov, half-drunk in a Petersburg tavern, asks a stranger whether he understands what it means for a man to have nowhere left to turn. In our villages the only office that ever finds its way to your door is the one that sends the bill. A law, which on paper seemed skewed in the first place, is further tilted by Section 57 of the same Act, which requires a licensee who has failed to meet the standards of performance as specified by the regulator to pay compensation to the affected consumer, as the Commission may determine. The Centre's Electricity (Rights of Consumers) Rules, 2020, however, views round-the-clock supply as a right as against the concession it has as a distribution company. May I ask in all earnestness how many households in Meghalaya have received a single paisa for any outage? I have been in the profession of law long enough to know when a right is there primarily to be invoked. The Greeks told of Prometheus, who stole fire from the gods, gave it to people for nothing, and was chained to a rock for his trouble. Meghalaya has quietly rewritten the myth. Here the fire is sold, not given... and it's the buyer who ends up chained. So, questions galore! None of them are rhetorical, as the answers, for a change, are tucked safely in the archives of Lumjingshai. How many hours of supply did each of the feeders in Ri-Bhoi and East Khasi Hills actually supply last month, and why is that number not in the public domain at the same time as the bill? If the load shedding is indeed a planned maintenance schedule, where is the detailed breakdown for different localities, and why does it so often omit the specific names of the feeders being affected? The Chief Minister himself had valued the Rs 900 crore project of the RDSS last December; when exactly is it going to be completed, and who will be held responsible if it doesn't happen? Why must families pay for a full month's fixed charge when they have received only half a month's supply, and will the MSERC consider a pro rata adjustment, or even a hearing, on the issue? And finally, is there a single instance in which the MSERC has invoked Section 57 of the Electricity Act against the MePDCL? Any citizen can raise these questions under the RTI Act. I expect they will be raised. Our grandmothers have a story about darkness as well. When Ka Sngi, the sun, was away in a cave and the world was plunged into darkness, the creatures did not send each other bills for the time they were in the cave. They called a dorbar and debated the matter before sending the rooster to coax her out. Nobody in that tale made the mistake of believing the darkness was a service. I call upon the Government of Meghalaya to show the same degree of basic common sense in raising this issue: bring back the light, and in the meanwhile, stop asking us for rent for the dark. (The writer is a practising Advocate, Trade Unionist & Ethicist from Ri Bhoi District)
Natrona County commissioners talk site tours, draft permit conditions for Prometheus data center proposal
CASPER, Wyo. -- On Tuesday, Natrona County commissioners spoke about recent site tours and reviewed 15 draft permit conditions for the proposed 1.5-gigawatt Prometheus Hyperscale data center. During the board's afternoon work session, county Development Director Sabrina Kemper shared conditional use permit rules borrowed from Uinta County, where Prometheus plans a similar campus. "Just kind of looking for feedback on those conditions to see where we're at," Kemper said, asking if the board wanted to use the framework or start over. Commissioners urged caution with the rules, with Commissioner Casey Coates pointing out that the Uinta County project has not yet been built. The board also questioned where developers will get the water needed for road work and dust control during site construction. Nicolaysen once again announced he would recuse himself from future decisions, telling the board he cannot vote on the project because the new proposed site on the Falls Ranch property south of Interstate 25 still borders his family's property. During a recent site tour, he realized the footprint sits next to his aunt's property off Hat Six Road. "So my conclusion is that I have a conflict of interest and that I won't be voting on this matter if and when it comes before the commission while I'm a commissioner," he said. He said he plans to step down to the public podium to speak as an affected landowner instead. Nicolaysen also questioned whether the county should zone the entire 1,000-acre area as industrial or keep the footprint smaller. Primary access for the site is planned for a new Interstate 25 interchange west of Big Muddy Creek. Commissioners Dallas Laird and Dave North reported on their own site visit last week, separate of the site tour Nicolaysen attended. Laird said the land sits in a low draw that would shield the facility from neighboring properties. North said he was pleased with the location after seeing it firsthand. Commissioners reiterated that Evansville-based Mesa Power Solutions will supply stationary natural gas generators for the campus. North said those generators would likely run quieter than the Jenbacher J620, which Prometheus had previously said it would use. Mesa expects to hire at least 25 full-time technicians to maintain the equipment on-site. Laird compared the data center proposal to the oil refineries that once drove Casper's economy, saying that the community weathered industrial pollution in exchange for growth. "Those were polluting businesses. They polluted the river. They polluted the air and all that, and Casper survived it," he said, adding it will be up to the commissioners to set parameters to protect county residents. "I am fixated on what that will do for this community if we really do get $50 million to $100 million in taxes. We can hire the people we need, or we can run people out of town. It's kind of what the refineries did for Casper, really." Still, Laird stressed that county officials cannot act on promises alone. "I also have a statement -- it doesn't mean anything till it's in writing, and we don't have anything in writing yet," he said. The discussion follows weeks of debate after Prometheus founder Trenton Thornock and Build Wyoming Director Eric Schlidt pitched the 1.5-gigawatt campus on 940 acres of the Falls Ranch, owned by Texas billionaire Russell Gordy. Developers asked for an industrial park zoning designation to bypass review by the Wyoming Industrial Siting Council. Neighbors and conservation groups have pushed back against the project. Residents have raised concerns over round-the-clock generator noise, air pollution, light, water use and falling property values. Laird said Gordy was along for his site tour last week. "I think it'd be a good idea for him to address the public to see who who this person is because he doesn't want ruin his ranch," he said. "I think he said he there's 17,000 acres there and they're going to use about a thousand. "He's a really nice person. And he doesn't want to hurt anybody," Laird added. County officials said Prometheus has not yet filed a formal application. Any official proposal must first go through the Natrona County Planning and Zoning Commission and public hearings before commissioners take a final vote.
