News & Updates
The latest news and updates from companies in the WLTH portfolio.
Vercel Open-Sources durable-harness for Crash-Proof Coding Agents
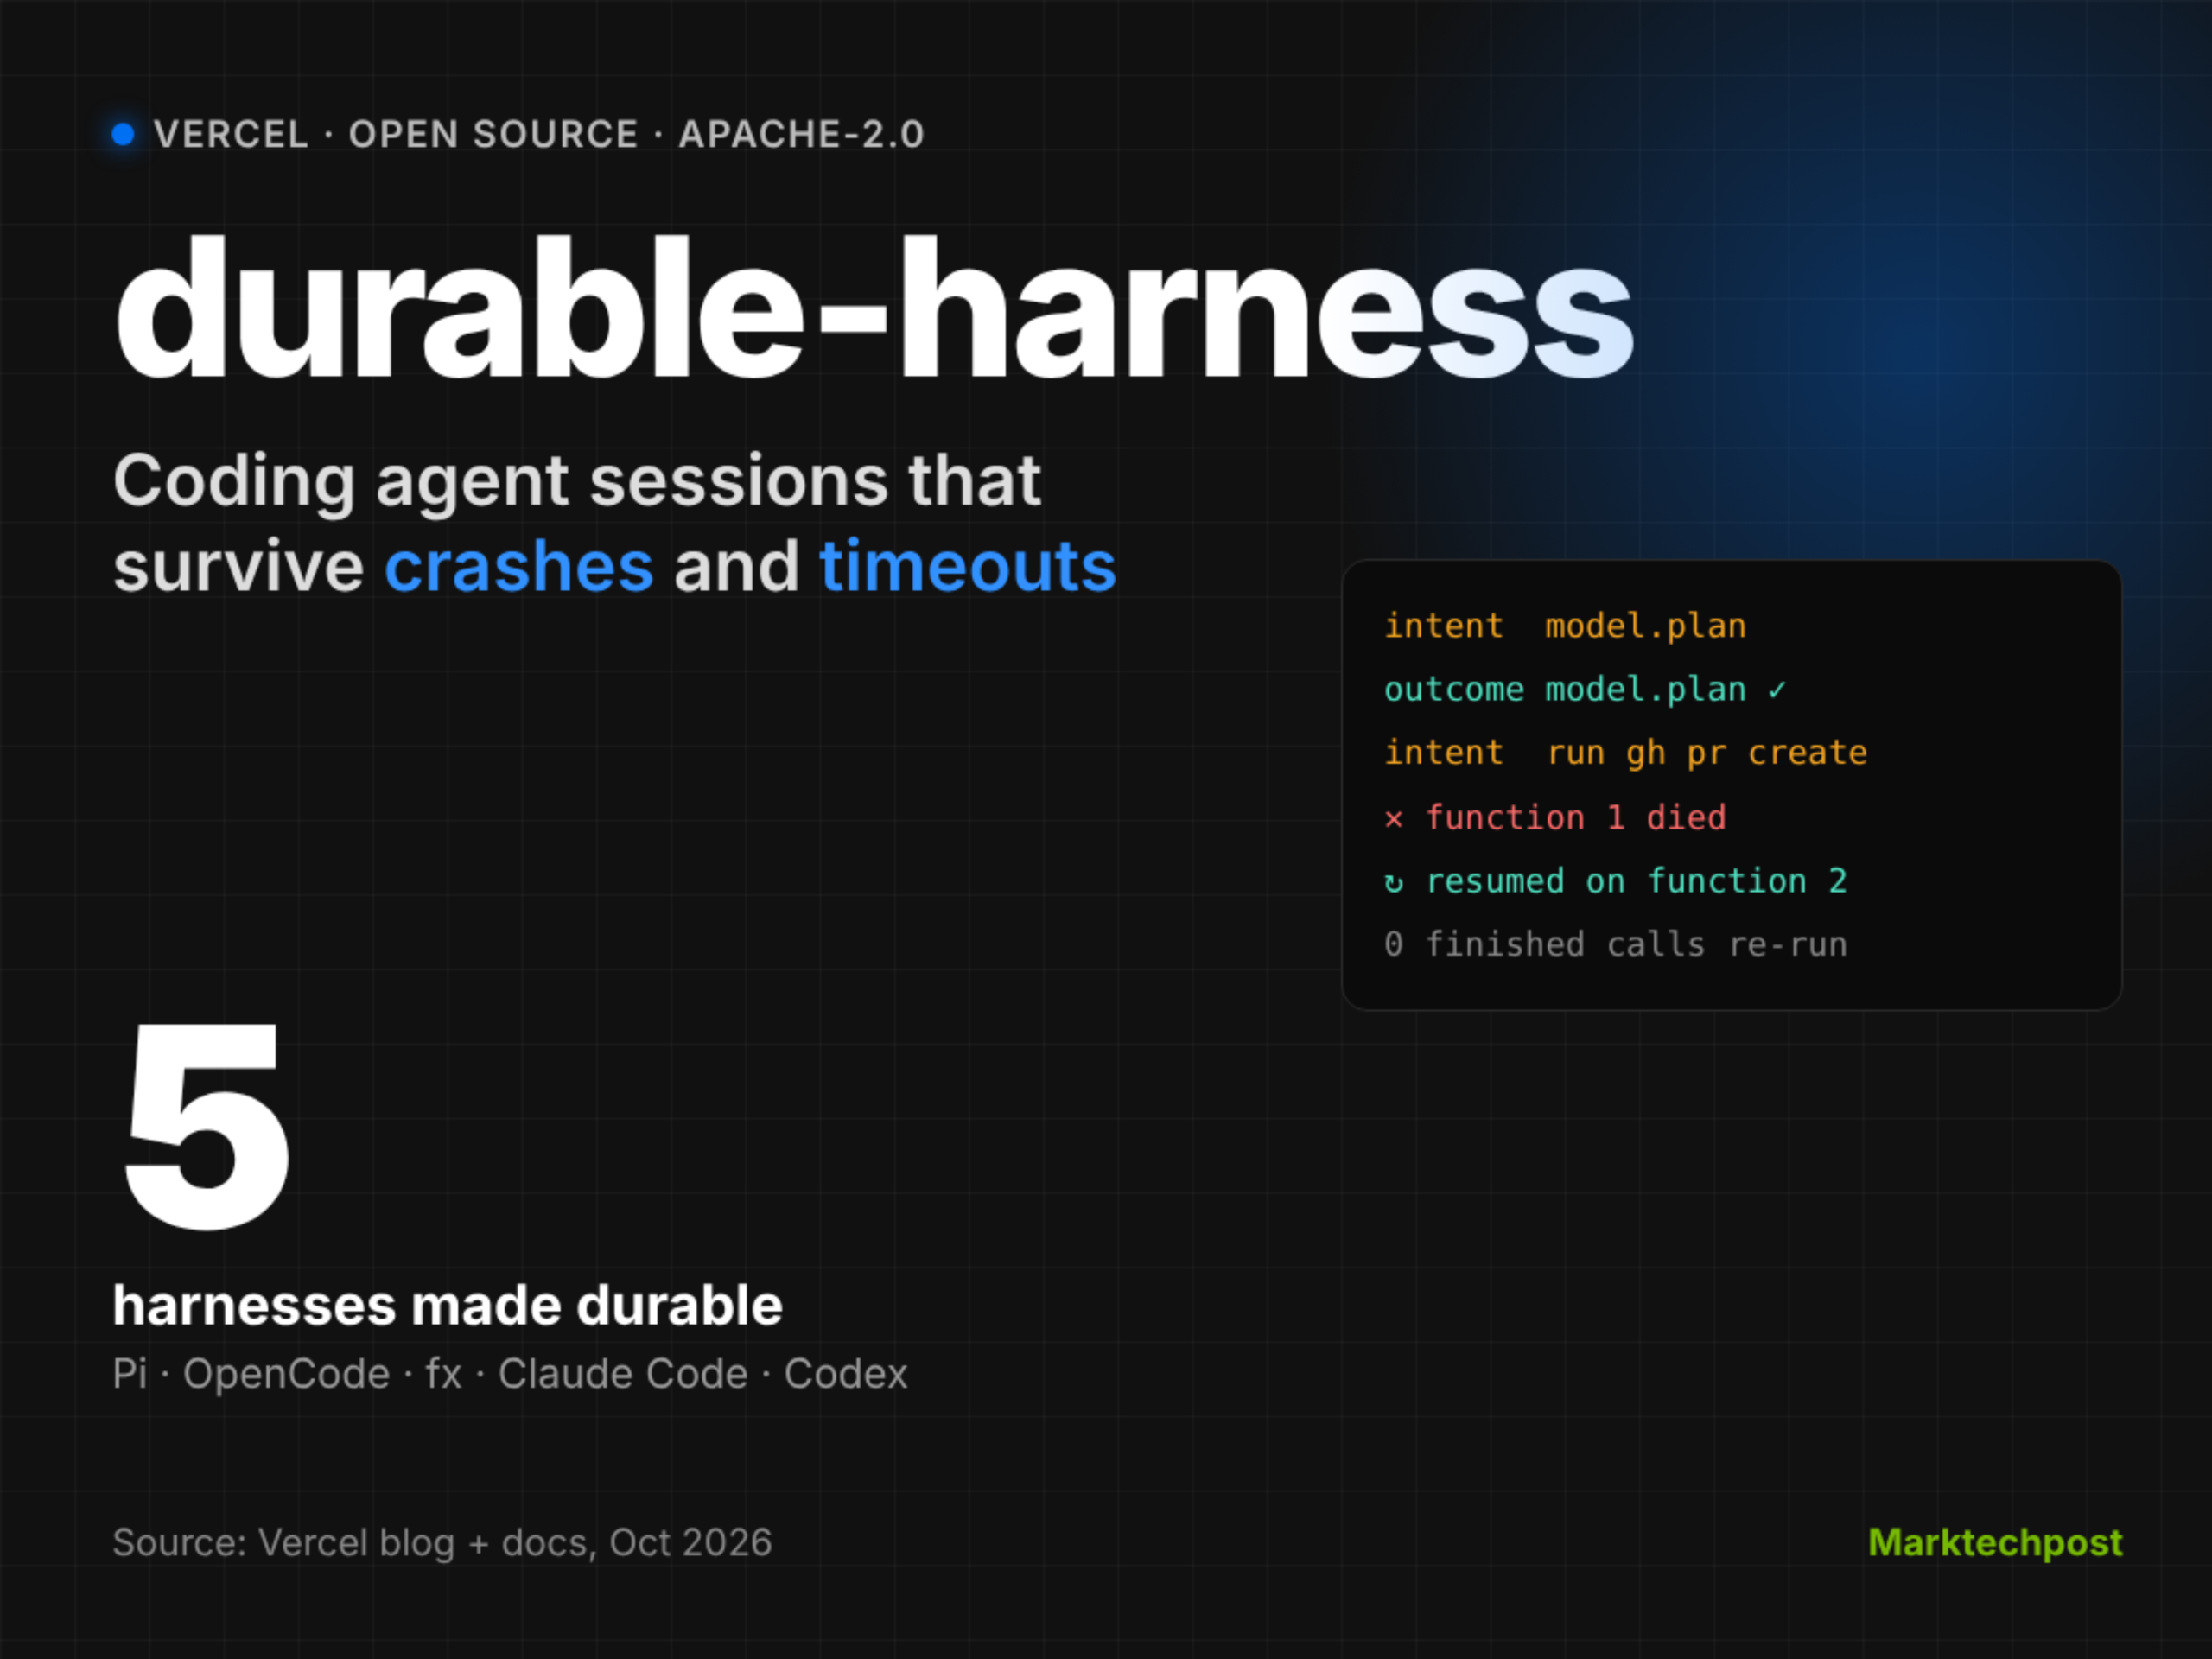
Vercel has released durable-harness, an open-source package that keeps coding agent sessions alive through crashes and timeouts. Vercel durable-harness wraps existing harnesses, including Pi, OpenCode, Claude Code and Codex, without changing them. Each session lives in a durable log. A dead function no longer means lost work. For teams moving agents off laptops and into the cloud, that closes a real gap. TL;DR * Size: npm package, version 0.0.x, Apache-2.0. Adapters cover 5 harnesses: Pi, OpenCode, fx, Claude Code, Codex. * Runs on: Vercel Functions plus Vercel Queues, Node.js 22+ with Postgres, or laptop files. Claude Code and Codex need a Vercel Sandbox. * Performance: No latency or throughput benchmarks published. All recovery claims are self-reported by Vercel. * Best: Finished model and tool calls are read back from the log, never re-run or billed twice. * Worst: Experimental 0.0.x API. Claude Code and Codex run only in a Vercel Sandbox, even self-hosted. What is durable-harness? durable-harness is a set of adapters from Vercel that store a harness session in a Workflow SDK World. A World bundles storage, a queue and a stream behind one interface. The package uses the same machinery that powers Vercel's Workflow SDK. Why do coding agents lose work in the cloud? Harnesses like Pi and Claude Code were designed as long-lived local processes. They keep the session in memory. Locally, the workspace and history sit on the same disk, so resuming takes 1 prompt. In the cloud, a VM with persistent storage does not track which calls completed. Vercel team notes a failed turn or network error then means lost work. How does durable-harness work? It writes each step of a turn to a durable log. Before a model or tool call runs, it records an intent. When the call finishes, it records the outcome. Each turn is backed by a message on Vercel Queues. If the function dies, the queue hands the turn to a new function. That function reads the log and continues. After a crash, the log shows what finished, what was running and what never started: * Completed calls are read from the log, so finished model tokens are not billed again. * replay: 'safe' tools, such as lookups, can run again. * replay: 'never' tools, such as refunds, never run twice. The model is told the call may have happened. Harness session files are mirrored into the log as well. That covers Claude Code's transcript, Codex's rollout and OpenCode's event store. Where do files and shell commands run? Model-chosen commands never run on the function's own disk. The tools docs list 3 workspace options: * keeps files in the session log, with a bash-compatible shell and no network. It holds about 500 files. * keeps scratch files in memory and clears them every turn. * gives each session a Vercel Sandbox, with /workspace on a Drive. Typed JSON documents, such as a to-do list, also live in the log. Each holds at most 64 KB. Where can you run durable-harness? The agent code stays the same across Worlds: * Vercel: the Vercel World, with every session traced in Agent Runs. * Local: files on your machine, with no configuration. * Self-hosted: the Postgres World, version 5.0.4 or later, on Node.js 22+. Vercel's blog also lists MongoDB, Redis and Turso. 2 environment variables, WORKFLOW_TARGET_WORLD and WORKFLOW_POSTGRES_URL, move an agent to Postgres. How does durable-harness compare? Key Takeaways * durable-harness logs every model and tool call, then resumes crashed turns on a new function. * Finished calls are never repeated, so tokens are not billed twice. * Pi and OpenCode run in your function; Claude Code and Codex need a Vercel Sandbox. * Self-hosting works with 2 env vars and a Postgres World. * It is 0.0.x and experimental, with no published benchmarks. Check out the GitHub repo, docs and Vercel's announcement. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don't forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
TypeSafe's Jev becomes Vercel AI Gateway's fastest-adopted model ever - Startup Fortune
Vercel, Cloudflare, LangChain and Langfuse integrated Jev within three days of its September 15 launch, and TypeSafe's seed round came in at $40 million, led by DCVC, backing ex-OpenAI researcher Diogo Almeida. A model that cannot write a single sentence just spread across Vercel's AI Gateway faster than anything else the platform has shipped, because production software increasingly needs a verdict, not a conversation. Within 24 hours of going into early access, TypeSafe AI's new model Jev was running on nearly 13% of Vercel AI Gateway's paid teams. According to Vercel's own changelog and reporting from The Next Web, that adoption curve was roughly double what GPT-5.6 managed in its first day on the gateway and about six times faster than Fable 5.1. Vercel, Cloudflare, LangChain and Langfuse had all wired Jev into their stacks within three days of its September 15 launch, per AI Weekly's rundown of the rollout. Here's the part that makes it strange: Jev can't hold a conversation. Ask it to write an email and it has nothing to say. TypeSafe built it to do one thing, take in whatever state your application is already tracking, a support ticket, a user's recent actions, a risk flag, and return a typed answer: a Boolean, a Score, or a Choice, each with a probability attached. No prose to parse. No regex pulling a verdict out of a paragraph. No prompt engineering a chatbot into behaving like a classifier. Anyone who has shipped an LLM feature knows the real cost isn't the model call. It's everything downstream of it: validating that the model actually returned JSON, catching the times it didn't, writing a fallback for when the "yes or no" answer comes wrapped in three sentences of hedging. Jev's pitch is that this layer simply doesn't need to exist. Feed it structured state, get a typed output back, wire it directly into your routing logic. That's why Vercel frames the integration around ticket routing, tool selection, and agent risk checks, the unglamorous plumbing that sits inside every serious agent pipeline and rarely gets a headline of its own. The economics reinforce the pitch. TypeSafe's own benchmark numbers put Jev at up to roughly 194 times faster and 445 times cheaper than frontier LLMs on its internal workflow evaluations, with responses landing in 70 to 500 milliseconds. Pricing runs at $0.042 per million input tokens, and output tokens are free, which makes sense once you realize there's no generated text to charge for. A model like this doesn't compete on creativity. It competes on being cheap enough and fast enough to call on every single request without anyone noticing the bill. System One Models Explained - What Are They and Why Should Founders Care A System One model answers a typed question with a probability in one pass instead of writing a paragraph. This guide covers how they differ from LLMs, what Jev, Laya and Clef offer, a worked cost example, and how to test one on your own traffic first. - system one models for faster ai inference costs - why founders should use system one ai models Diogo Almeida is the reason this isn't just another "fast, cheap inference" startup. He's a former OpenAI researcher credited as a co-inventor of the RLHF technique that shaped how ChatGPT behaves, and he spent two years in stealth building TypeSafe before Jev ever saw daylight. That pedigree bought the company a $40 million seed round led by DCVC, and it's also why the launch got taken seriously by infrastructure players like Vercel and Cloudflare instead of being dismissed as a novelty. When someone who helped define the alignment techniques behind the biggest chatbot on earth turns around and builds something that deliberately can't chat, people pay attention to what he thinks the next bottleneck actually is. What he seems to think is that the chatbot interface was never the point for a huge share of production AI spend. A support platform routing a ticket doesn't need a model to explain its reasoning in flowing English. It needs a confidence-scored answer it can act on in under half a second, at a cost low enough to run on every ticket that comes in, not just the hard ones. Jev's adoption curve suggests a lot of engineering teams had already reached that conclusion on their own and were simply waiting for someone to build the thing. That's the real signal underneath the adoption numbers. "Decision models" aren't a new flavor of chatbot competing for leaderboard position against GPT-5.6 or Fable 5.1. They're a separate category entirely, sitting lower in the stack, doing the boring typed work that agent pipelines have been bolting together out of prompt hacks and brittle output parsers. If Jev's early numbers hold up as it exits early access, the next wave of AI infrastructure fights might not be about which model writes the best paragraph. It might be about which one never has to write one at all. This article is posted in AI News, check it out for more related stories. Join the discussion Open in the community → Reply Almost there. Sign in and your reply posts straight away.

Vercel Makes Drives Generally Available, Puts Two Agent Tools in Beta | EconoTimes
Sandbox customers on Hobby, Pro and Enterprise plans can use Drives. At its Oct. 15 Ship 2026 event, Vercel made persistent Drives generally available and put Daemons and MCP Events in public beta, adding storage and background processing options for agent software. The release spans three parts of agent development. Daemons run background jobs, Drives retain files between Sandbox sessions, and MCP Events route notices from compatible services to apps. Drives are generally available; Daemons and MCP Events are in public beta. Vercel's Daemons use Fluid compute to process jobs arriving from queues, databases or external systems, without exposing an HTTP endpoint. Teams choose how many instances to run in each region, and Vercel brings up replacements when one stops or crashes. Drive content lives outside the Sandbox runtime, so ending a session does not remove the files. Developers may reconnect a Drive during a later session. They can also branch from one Drive into writable copies, allowing different workers to start from common files but keep changes separate. The feature is generally available on Sandbox's Hobby, Pro and Enterprise plans. Vercel Connect now offers MCP Events in public beta. Through Connect, an app can be set up to receive webhook notifications from an MCP server that supports the feature. The service administers subscriptions, validates incoming messages and sends events with authentication. Together, the releases add options for persistent files, unattended jobs and event notifications in agent workflows. Vercel introduced the features at Ship 2026 on Oct. 15.
How Vercel is rethinking go-to-market with AI
Vercel is pioneering an AI-powered go-to-market approach, drastically reducing human sales and support teams by integrating AI agents for qualification and resolution. This post also explores a contrarian view on traditional one-on-one meetings, advocating for real-time, asynchronous communication over scheduled discussions. AI agents can reduce a 10-person sales team to one person and an AI agent Vercel is demonstrating a paradigm shift by integrating AI agents into go-to-market functions, allowing a 10-person sales team to scale down to one person supported by an AI agent. AI handles inbound qualification and 91% of support resolutions, freeing human teams to focus on complex prospecting and identifying product problems. This creates a leaner BDR, support, and RevOps structure, improving the headcount-to-revenue ratio. We get into why she walked away from one of the most valuable private companies in the world, what it's like to take a 10-person sales team down to one person and an AI agent, and the brutally honest feedback that reshaped how she leads. Scheduled one-on-ones can hinder real-time problem solving The speaker adopts an 'anti-one-on-one' stance, particularly for leadership teams and new managers. This perspective suggests that urgent issues are often resolved immediately through platforms like Slack, diminishing the impact of scheduled one-on-ones for critical discussions. It challenges the conventional belief that regular, scheduled meetings are always the most effective management tool. And we have like a leadership team and you know, new managers and I'm I've I would say I'm also the like anti- one-on-one. The founder-executive relationship is a professional marriage The relationship between an executive and the founder is paramount, outweighing other factors for company success. It is likened to a 'professional marriage,' requiring significant time investment, open communication, and the capacity for productive disagreement. This strong bond is essential for navigating challenges and ensuring strategic alignment at the highest levels of the company. my general advice maybe is wrong but my advice my opinion is the relationship with the founder is maybe 10 times more important than every else everything else on the list. Operators must prioritize predictable output over minor issues An operator's job is to build systems that consistently produce predictable output, specifically revenue. This requires disciplined prioritization, where operators must actively decide if a minor issue is a critical priority (P0) contributing to the system's next strategic evolution. They must learn to overlook minor imperfections, like fixing commas in a document, to focus on higher-impact initiatives. I think so because like I'm my job is to be an operator.